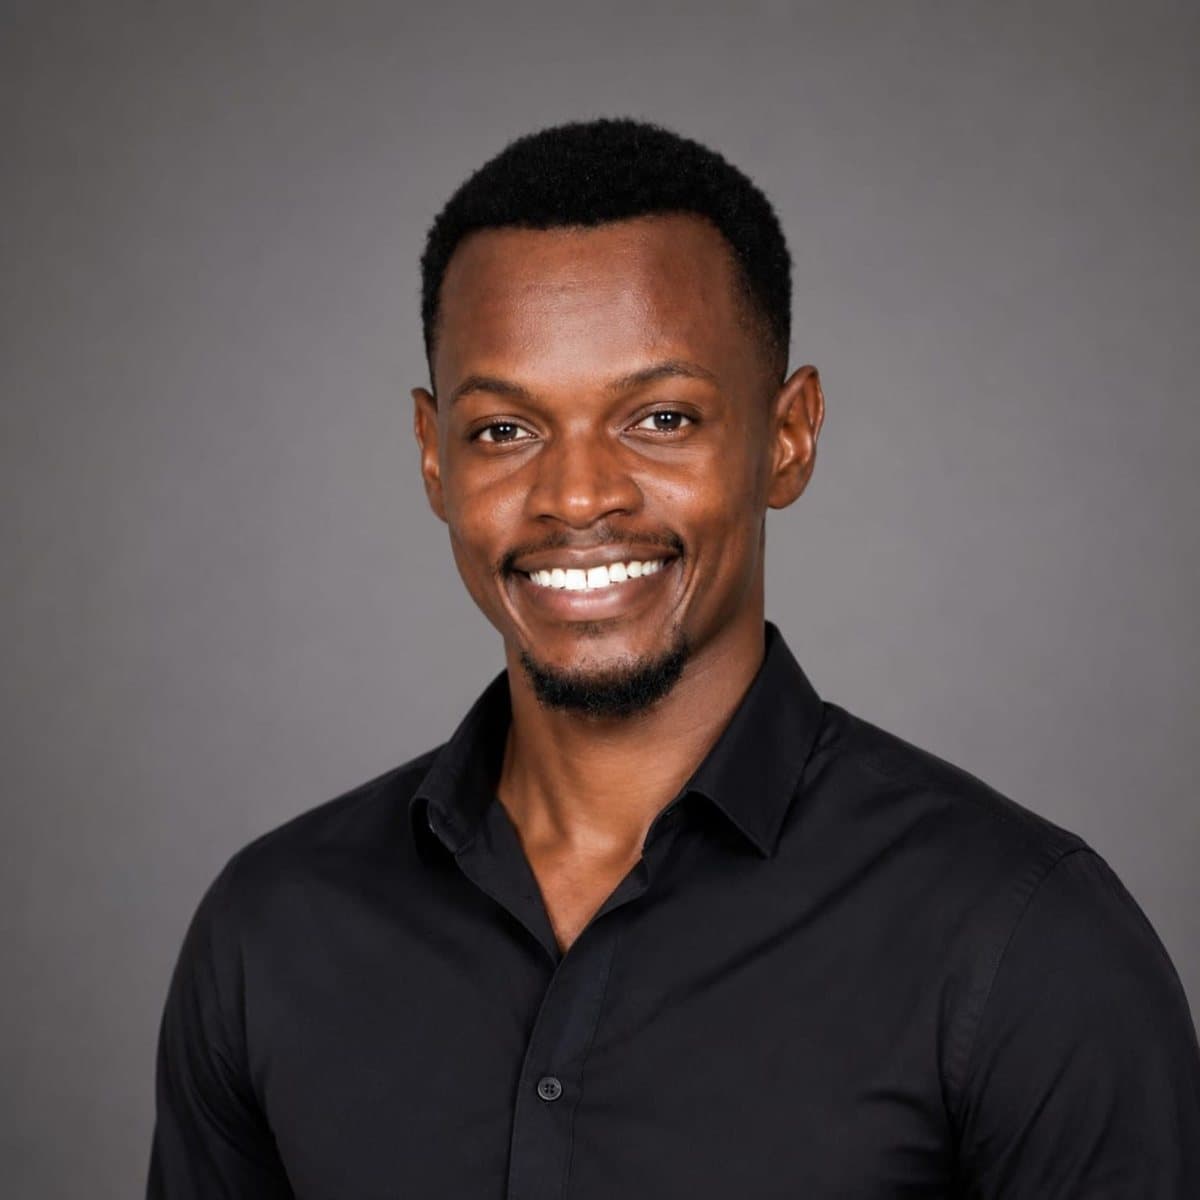
Collins Nyagaka

AI & Machine Learning Engineer

I build ML and LLM systems that hold up under honest evaluation, from fraud models tested on future data to legal search that refuses to guess.

I

Problem

A model that looks great until it meets next month's data.

Shuffled splits let it learn from the future, so the score in the notebook never shows up in production.

A legal answer that cites a section that isn't there.

Retrieval found something close enough, and nothing checked whether it was close enough to trust.

One firm's records visible to another.

Isolation lived in the interface, and the database underneath let anyone ask for anything.

II

Method

Collins Nyagaka, smiling, in a black shirt against a grey studio background
Collins Nyagaka, Nairobi. AI and machine-learning engineer.
  1. Evaluate on data the model hasn't seen

    Time-ordered splits, held-out questions, and intervals instead of single numbers.

  2. Enforce isolation in the database, not the UI

    Row-level security, tested by attacking it from another tenant.

  3. Say what isn't done

    Every case study ends with its limits, including the targets it missed.

  4. Ship with tests and security checks

    CI runs the evaluation, the secret scan and the accessibility checks on every change.

III

Work

LegalAI Kenya, legal research for advocates

A multi-tenant research workspace over 61,683 passages of Kenyan law that refuses to answer when the evidence is weak.

Read the case study

hit@10, LegalAI live index
0.303
300 litigation questions held out of the index, run against the live index. Search settings were tuned on these questions. The previous keyword engine scored 0.025.
hit@10 gain, untuned set
0.153 to 0.183
The next 300 questions, which played no part in tuning. The honest test of the tuning. The gain held, on a harder slice.
off-topic queries refused
34 of 40
40 off-topic or gibberish queries. At an evidence floor of 0.45, about 97% of real questions still pass. A 0.35 floor answered 26 of the 40 and was rejected.
tenant-isolation probes passed
37 of 37
Attack suite run against the staging database. Staging, not production. No SOC 2 or ISO 27001 certification is held.

Real-time credit-card fraud detection

A LightGBM fraud model, evaluated on transactions it never saw in training, with 1.4 ms p95 in-process model inference.

Read the case study

F1, fraud holdout
0.80
Time-ordered holdout, 42,722 transactions. Bootstrap 95% CI 0.71 to 0.88. The project's own target was 0.85, and this misses it.
Recall, gate failed
0.75
Time-ordered holdout, at the tuned threshold. Bootstrap 95% CI 0.63 to 0.86. The 0.85 recall gate failed.
p95 in-process inference
1.4 ms
One in-process predict call per row, on precomputed features. Not API latency. Feature engineering and the network add to it.

ComplianceGuard, anti-money-laundering monitoring for Kenya

A pre-pilot platform that turns M-Pesa-style payments into holds, cases and drafted reports under Kenyan anti-money-laundering law.

Read the case study

AML typologies, synthetic data
35
Versioned JSON registry, exercised by a synthetic M-Pesa-style generator (seed 42). Synthetic data only. The rules have never scored a real institution's transactions.
sanctions names, live sync
285,503
Live OFAC SDN, UN Consolidated and OpenSanctions downloads on 2026-10-20, after deduplication. One full download, checked against a SHA-256 manifest. There's no incremental update feed yet.

Production AI Reference Template

A FastAPI reference for multi-tenant LLM workflows, where tenant scope comes from the login and the agent loop is bounded.

Read the case study

tests passing, AI template CI
49
The repository's test suite in CI at commit 3b800c1 (2026-09-08). External services (the model, the OpenKB sidecar, web search) are mocked, so no test makes a live model call.

GEO-AI cropland mapping from satellite data

Crop versus non-crop from Sentinel-1 and Sentinel-2 data in two regions, with an honest look at where the evaluation flattered the model.

Read the case study

accuracy vs 0.703 baseline
0.745
200 held-out labelled points (stratified random 20% of 1,000 across Fergana and Orenburg). Guessing "non-crop" for every point scores 0.703 on this data, and a random split lets nearby points leak between train and test.

More projects

Now try one.

IV

Score a transaction

A real transaction from the held-out test data, with the 10 before it. Score it, change it, score it again.

V

Colophon

Every figure on this page, with what it was measured on and where to check it.

Evidence for every figure on this page
FigureWhatMeasured onCaveatProjectSource
0.303hit@10, LegalAI live index300 litigation questions held out of the index, run against the live indexSearch settings were tuned on these questions. The previous keyword engine scored 0.025.LegalAI Kenya, legal research for advocatesPrivate work
0.153 to 0.183hit@10 gain, untuned setThe next 300 questions, which played no part in tuningThe honest test of the tuning. The gain held, on a harder slice.LegalAI Kenya, legal research for advocatesPrivate work
34 of 40off-topic queries refused40 off-topic or gibberish queriesAt an evidence floor of 0.45, about 97% of real questions still pass. A 0.35 floor answered 26 of the 40 and was rejected.LegalAI Kenya, legal research for advocatesPrivate work
37 of 37tenant-isolation probes passedAttack suite run against the staging databaseStaging, not production. No SOC 2 or ISO 27001 certification is held.LegalAI Kenya, legal research for advocatesPrivate work
0.80F1, fraud holdoutTime-ordered holdout, 42,722 transactionsBootstrap 95% CI 0.71 to 0.88. The project's own target was 0.85, and this misses it.Real-time credit-card fraud detectionRepository file (opens in new tab)
0.75Recall, gate failedTime-ordered holdout, at the tuned thresholdBootstrap 95% CI 0.63 to 0.86. The 0.85 recall gate failed.Real-time credit-card fraud detectionRepository file (opens in new tab)
1.4 msp95 in-process inferenceOne in-process predict call per row, on precomputed featuresNot API latency. Feature engineering and the network add to it.Real-time credit-card fraud detectionRepository file (opens in new tab)
35AML typologies, synthetic dataVersioned JSON registry, exercised by a synthetic M-Pesa-style generator (seed 42)Synthetic data only. The rules have never scored a real institution's transactions.ComplianceGuard, anti-money-laundering monitoring for KenyaPrivate work
285,503sanctions names, live syncLive OFAC SDN, UN Consolidated and OpenSanctions downloads on 2026-10-20, after deduplicationOne full download, checked against a SHA-256 manifest. There's no incremental update feed yet.ComplianceGuard, anti-money-laundering monitoring for KenyaPrivate work
49tests passing, AI template CIThe repository's test suite in CI at commit 3b800c1 (2026-09-08)External services (the model, the OpenKB sidecar, web search) are mocked, so no test makes a live model call.Production AI Reference TemplateRepository file (opens in new tab)
0.745accuracy vs 0.703 baseline200 held-out labelled points (stratified random 20% of 1,000 across Fergana and Orenburg)Guessing "non-crop" for every point scores 0.703 on this data, and a random split lets nearby points leak between train and test.GEO-AI cropland mapping from satellite dataRepository file (opens in new tab)

11 figures from 5 projects.

If this is the kind of work you need, Email Collins and say what you're building.